Yiyao Zhang
I am a third-year Ph.D. student in Computer Science at Nanjing University and a member of the Theory Group, advised by Prof. Yitong Yin. I earned my B.S. in Computer Science from Nanjing University in 2024.
Research Interests: Sampling and Counting; Learning Theory; Probability Theory
Education
Nanjing University
B.S. in Computer Science
Publications
Authors are listed alphabetically unless otherwise stated.
Preprints
-
Single-Variable Connectivity in Random k-SAT.
Abstract
We resolve longstanding questions about connectivity, reconstruction, and looseness in random
 -SAT, for sufficiently large fixed as the number
 of variables tends to infinity.
Single-variable connectivity up to reconstruction. At clause densities up to
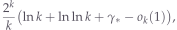
a polynomial-time algorithm joins a typical pair of satisfying assignments with high probability, using
 single-variable flips that preserve satisfiability. Here
 arises from a refined tree-reconstruction analysis.
Settling the reconstruction threshold. Building on the tools developed for connectivity, we determine the clustering threshold defined by the reconstruction criterion to be
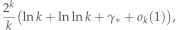
below the classical cavity prediction with constant term
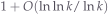 .
Shattering before rigidity. We locate the looseness–rigidity transition at a higher density, matching the classical cavity prediction for clustering:
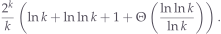
Below the transition, we establish a stronger form of looseness: any variable of a typical solution can be reversed by logarithmically many single-variable flips that preserve satisfiability. Above it, reversing most variables of a typical solution requires changing linearly many variables (rigidity). Yet throughout an interval between reconstruction and rigidity, the solution space already splits into groups of exponentially small relative size separated by linear Hamming distance and linear energy barriers (shattering), while logarithmic looseness persists.
These results resolve the giant-component and logarithmic-looseness conjectures of Chen–Mani–Moitra (SODA 2023), the sublinear-looseness conjecture of Achlioptas–Coja-Oghlan (FOCS 2008), and the reconstruction formulation of the clustering problem of Krzakala–Montanari–Ricci-Tersenghi–Semerjian–Zdeborová (PNAS 2007).
-
An Õ(n2)-Time Sampler for Zero-Field Ferromagnetic Ising Models.
Abstract
We give an approximate sampler for ferromagnetic Ising models with no field on arbitrary graphs that runs in time
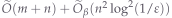 , where and
 are the numbers of vertices and edges, respectively, and
 is the approximation error. Our approach combines Benczúr–Karger cut sparsification with a new mixing time analysis of the Glauber dynamics for the random-cluster model. The mixing time analysis features a new monotone edge-count Poincaré inequality.
-
Optimal Simulated Annealing for Partition Function Estimation.
Abstract
In this note, we give a simple analysis of a non-adaptive simulated annealing algorithm for estimating the partition function of Gibbs distributions. This yields the most efficient reduction of this kind so far. We also establish lower bounds for both general and non-adaptive algorithms, showing that our algorithm is optimal over a broad range of parameters.
-
Learning CNF Formulas from Uniform Random Solutions: Near-Tight Sample Complexity for Valiant's Algorithm.
Abstract
We revisit Valiant’s algorithm (Commun. ACM’84) for learning
-variable CNF formulas with clause size and variable degree  from i.i.d. uniform random solutions in the local lemma regime. For fixed
 , under
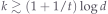 , Valiant’s algorithm achieves total variation error with
 sample complexity. For
 , we prove a matching lower bound for Valiant’s algorithm. At
 (covering
 ), we show Valiant’s algorithm has optimal sample complexity up to logarithmic factors by an information-theoretic lower bound
 .
-
A Counting and Sampling Lovász Local Lemma.
Abstract
We establish counting and sampling analogues of the Lovász Local Lemma: we give efficient algorithms for approximately counting and exactly sampling satisfying assignments of general constraint satisfaction problems (CSPs) in the local lemma regime
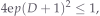
where
 is the maximum constraint violation probability and
 is the maximum dependency degree.
This condition is tight up to constant factors under
 , matching known hardness bounds for counting and sampling in natural subclasses of CSPs. Our key ingredient is a novel
 -tree expansion for constraint marginal probabilities that exhibits exponential decay of correlations throughout this regime.
This expansion yields deterministic polynomial-time approximate counting for fixed local parameters, randomized approximate counting with quadratic cost, and exact sampling in expected near-linear time when the local parameters are fixed.
Conference Papers
-
Learning AC0 under Locally Sampleable Graphical Models.
Abstract
The problem of learning constant-depth circuits holds profound implications for computational learning theory. In a seminal result, by introducing the low-degree algorithm, Linial, Mansour, and Nisan (J. ACM 1993) presented a quasipolynomial-time learner for
 under the uniform distribution. However, obtaining comparable learning guarantees for broader classes of correlated distributions has remained a longstanding challenge. Recently, Chandrasekaran, Gaitonde, Moitra, and Vasilyan (arXiv 2026) extended these guarantees to Gibbs distributions on bounded-degree graphical models with both strong spatial mixing and polynomial growth.
In this paper, we give a quasipolynomial-time learner for
under graphical models that admit efficient local samplers, circumventing the polynomial-growth requirement in prior work. The key ingredient is a new low-degree approximation for Gibbs distributions, established by simulating and suitably truncating the classical Glauber dynamics. As applications, this framework yields learners for two-spin systems, including the hard-core model and Ising model, on arbitrary bounded-degree graphs, in regimes approaching their respective sampling thresholds. -
Near-Optimal Parallel Approximate Counting via Sampling.
Abstract
The computational equivalence between approximate counting and sampling is well established for polynomial-time algorithms. The most efficient general reduction from counting to sampling is based on simulated annealing. In this approach, the counting problem is formulated as estimating the ratio
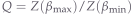 between partition functions
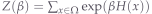 of Gibbs distributions
 over
 with Hamiltonian
 , given access to a sampling oracle for at any
 . The sample complexity (measured by the number of oracle calls) is typically expressed in terms of
 and
 , which respectively bound
 and . The best upper bound achieved by known annealing algorithms with relative error is
 . However, all known algorithms attaining this near-optimal complexity are inherently sequential, or adaptive: the queried parameters
 depend on previous samples.
We develop a simple non-adaptive algorithm for approximate counting using
 samples, as well as an algorithm that achieves samples with just two additional adaptive rounds, matching the best sample complexity of sequential algorithms. These algorithms naturally yield work-efficient parallel (RNC) counting algorithms. We discuss applications to several classic models, including the anti-ferromagnetic 2-spin, monomer-dimer and ferromagnetic Ising models.
-
Learning CNF Formulas from Uniform Random Solutions in the Local Lemma Regime.
Abstract
We study the problem of learning a
-variables -CNF formula  from its i.i.d. uniform random solutions, which is equivalent to learning a Boolean Markov random field (MRF) with -wise hard constraints. Revisiting Valiant’s algorithm (Commun. ACM’84), we show that it can exactly learn (1) -CNFs with bounded clause intersection size under Lovász local lemma type conditions, from
 samples; and (2) random -CNFs near the satisfiability threshold, from
 samples. These results significantly improve the previous
 sample complexity. We further establish new information-theoretic lower bounds on sample complexity for both exact and approximate learning from i.i.d. uniform random solutions.
-
Hyper-USS: Answering Subset Query over Multi-Attribute Data Stream.
Abstract
Sketching algorithms are considered as promising solutions for answering approximate query on massive data stream. In real scenarios, a large number of problems can be abstracted as subset query over multiple attributes. Existing sketches are designed for query on single attributes, and therefore are inefficient for query on multiple attributes. In this work, we propose Hyper-USS, an innovative sketching algorithm that supports subset query over multiple attributes accurately and efficiently. To the best of our knowledge, this work is the first sketching algorithm designed to answer approximate query over multi-attribute data stream. We utilize the key technique, Joint Variance Optimization, to guarantee high estimation accuracy on all attributes. Experiment results show that, compared with the state-of-the-art (SOTA) sketches that support subset query on single attributes, Hyper-USS improves the accuracy by 16.67× and the throughput by 8.54×. The code is open-sourced at Github.
Talks
-
Near-Optimal Parallel Approximate Counting via Sampling.
-
Learning CNF Formulas from Uniform Random Solutions in the Local Lemma Regime.
Visiting and Internship
The University of Hong Kong
Research assistant hosted by Asst. Prof. Weiming Feng.
Teaching Assistantship
Advanced Algorithms (Nanjing University)
Instructors: Yitong Yin, Shi Li, Jingcheng Liu.
Awards
- Presidential Special Scholarship for Doctoral Students
- Outstanding Undergraduate Student of Nanjing University
- National Scholarship for Undergraduate Students